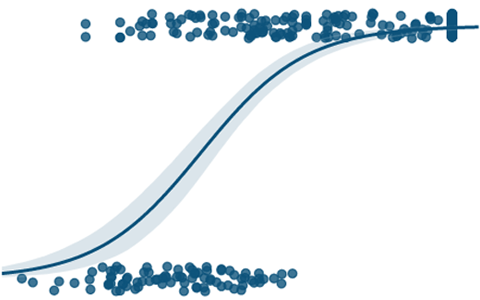
Logistic regression is a statistical procedure to estimate binary events. Thus, similar to linear regression, any number of independent variables (X) are used to calculate a dependent binary variable Y (with the instances 0 and 1). More precisely, logistic regression is used to estimate the influence of X on Y. For each regressor, a coefficient βi is estimated, usually by means of a maximum likelihood estimation. Coefficients describe the influence strength (value of the coefficient) and influence direction (sign of the coefficient).
Often, the curve of logistic regression runs like an S. The probability is plotted on the Y-axis, whereas the X-axis reflects a specific regressor variable.
The coefficients are transformed by necessary mathematical transformations. Therefore, they are no longer directly interpretable in their strength of influence – in contrast to linear regression. Hence, often the so-called “odds ratios” are formed, as these allow a simpler interpretation. Odds ratios describe the change in the probability ratio. Remember, it is not the same as the change in absolute probability!
Blog posts about the interpretation of the coefficients or the implementation of a logistic regression can be found here:
TowardsDataScience
Finally, it is advisable to pay more attention to the direction of influence rather than the strength of influence when interpreting the data.
The application of logistic regression is versatile and transferable to numerous business contexts. From predicting the churn of customers or employees to calculating response probabilities to marketing or sales campaigns. Applied to the sales context, this could mean estimating whether or not customers purchases a product (target variable Y). For example, age, number of logins, gender, and a customer score (for example, frequency of purchases and amount of purchases) can be used as regressors (X).
Purchase probability (0 or 1) = β0 + β1*Age + β2*Number of logins + β3*Gender + β4*Customer score
In the example above, it could be assumed that the number of logins and the customer score have a positive influence on the probability of closing a deal. Likewise, the more active (number of logins) a customer is, the higher his interest in the respective products tends to be. Similarly, the higher the sales volume of a customer (customer score), the greater the willingness to buy additional products (cross-selling). As a result, this could be verified with the help of logistic regression (at least at a correlative level).
Logistic regression is one of the supervised learning methods in machine learning, since the target variable (Y) is known. Logistic regression alone does not yet have any machine learning characteristics. These are added when different models are tested against each other and continuously updated with new data so that the model “learns”.
from sklearn.linear_model import LogisticRegression
reg = LogisticRegression().fit(X_train, y_train)
reg.coef
The code snippet is written in Python and based on the module scikit-learn.