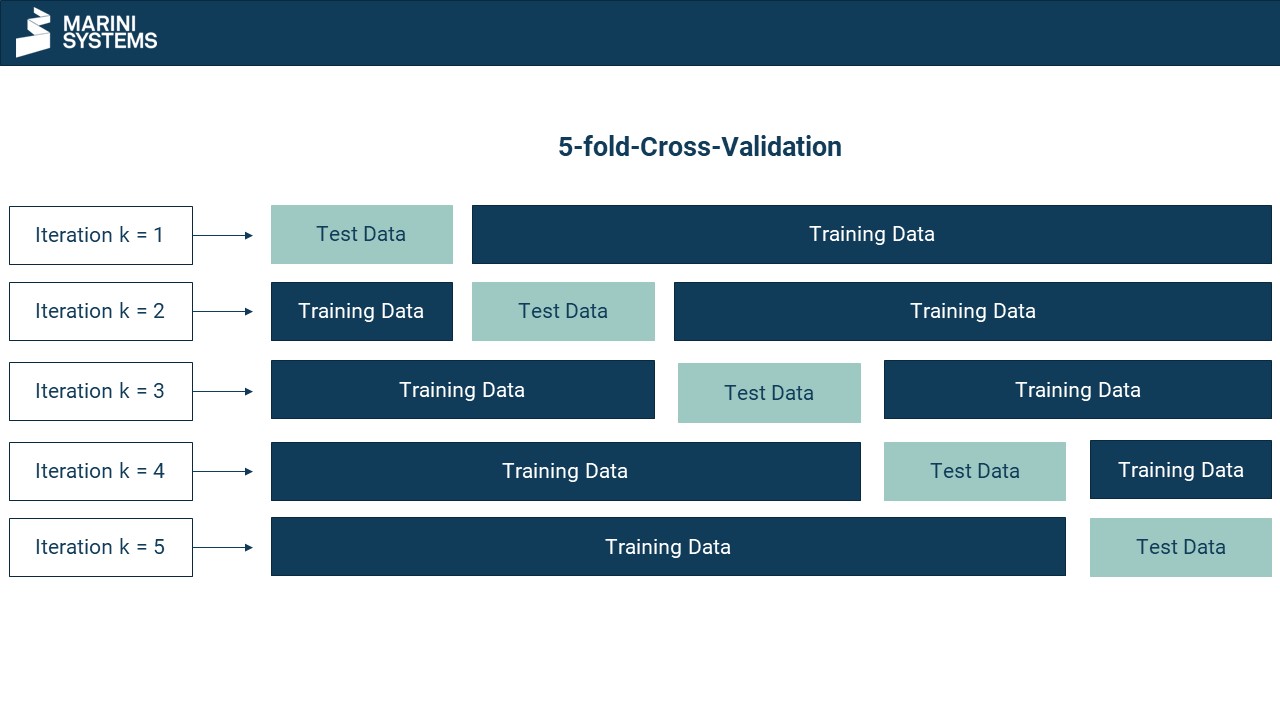
Cross-Validation is a procedure for the validation of models from data mining and machine learning.
The input data is prepared in Data Preparation according to current machine learning standards (pre-processing). Normally, the data is now split into training and test data set. Then the model is trained on the training data and evaluated on the test data. However, often an unfavorable split in training and test data can seriously lead to a miscalculated model. For example, the distribution of the target variable (target class) in both training and test data may be unequal, or the distribution of certain features may differ greatly. However, this is usually not a problem if the data sets are large enough. But when is the data set large enough?